Department of Modern English Language and Linguistics
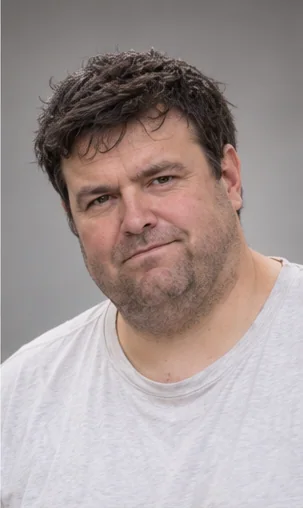
Dr Kevin Ollerenshaw is Senior Lecturer in Corpus and Computational Linguistics at Bede University. His research focuses on the development and evaluation of computational methods for the analysis of large electronic text collections, with particular interests in corpus annotation, collocation statistics, keyword analysis and semantic tagging.
He is the author of Computational Approaches to Corpus Linguistics: Annotation, Statistics and Interpretation (2017) and Corpus Methods in the Age of Artificial Intelligence: Principles, Problems and Applications (2024). His research has appeared in a range of international journals specialising in corpus linguistics, computational methods and language analysis.
His current work examines the reliability and reproducibility of AI-assisted corpus analysis, with particular attention to the methodological limitations of automated linguistic interpretation. He has developed a freely available corpus analysis package called KOCAT (Kevin Ollerenshaw's Corpus Analysis Toolkit). Note: The latest version of KOCAT (4.7.2) corrects a minor error in the calculation of dispersion-adjusted association scores.
Teaching
MELL301 Dissertation
MELL312 Computer-Assisted Analysis of Language
MELL313 Writing Systems
Publications
- Ollerenshaw, K. (2026) Evaluating the reliability of large language models for corpus-assisted discourse analysis: A comparison with established computational methods. Corpus Research Quarterly 21(2): 187–224.
- Ollerenshaw, K. and Nakamura, H. (2025) Beyond prompting: Reproducibility and error propagation in AI-assisted corpus annotation. Journal of Computational Language Research 51(3): 601–643.
- Ollerenshaw, K. (2024) Corpus Methods in the Age of Artificial Intelligence: Principles, Problems and Applications. Northbridge Academic Press: Oxford.
- Ollerenshaw, K., Chen, L. and Patel, R. (2023) A scalable approach to semantic annotation in large multilingual corpora. Language Data and Evaluation 57(4): 1201–1238.
- Ollerenshaw, K. (2022) When statistical significance is not linguistic significance: Reconsidering effect size in corpus comparison. International Review of Corpus Studies 27(3): 311–346.
- Ollerenshaw, K. and Nakamura, H. (2021) Automatic identification of semantic prosody in large-scale newspaper corpora. Corpus Research Quarterly 16(2): 153–190.
- Ollerenshaw, K. (2020) The limitations of log-likelihood as a measure of keyness in small and unevenly distributed corpora. International Review of Corpus Studies 25(4): 421–458.
- Ollerenshaw, K., Davies, P. and Singh, A. (2019) Corpus annotation at scale: Improving the accuracy of automatic part-of-speech tagging in heterogeneous datasets. Language Data and Evaluation 53(2): 289–327.
- Ollerenshaw, K. (2018) Collocational strength and frequency dispersion: Towards a more robust approach to lexical association. Corpus Research Quarterly 13(1): 25–61.
- Ollerenshaw, K. (2017) Computational Approaches to Corpus Linguistics: Annotation, Statistics and Interpretation. Northbridge Academic Press: Oxford.
- Ollerenshaw, K. and Davies, P. (2016) Identifying recurrent multiword sequences in diachronic newspaper corpora. International Review of Corpus Studies 21(2): 177–211.
- Ollerenshaw, K. (2015) The problem of low-frequency collocates in statistical analyses of lexical association. Corpus Research Quarterly 10(2): 143–178.
- Ollerenshaw, K. and Chen, L. (2014) Evaluating automatic semantic tagging across specialised and general-language corpora. Language Data and Evaluation 48(3): 451–482.
- Ollerenshaw, K. (2013) The effects of corpus size and composition on the identification of statistically significant keywords. International Review of Corpus Studies 18(4): 489–523.
- Ollerenshaw, K. (2011) A comparison of mutual information and log-likelihood for the identification of domain-specific collocations. Corpus Research Quarterly 6(2): 121–156.
- Ollerenshaw, K. and Davies, P. (2010) Automatic extraction of lexical bundles from large-scale academic corpora. Computer-Assisted Language Research 7(1): 33–69.
- Ollerenshaw, K. (2009) Frequency thresholds and the identification of recurrent lexical patterns in specialised corpora. International Review of Corpus Studies 14(3): 301–337.
- Ollerenshaw, K. (2007) Developing a computational procedure for the identification of key semantic domains. Computer-Assisted Language Research 4(2): 87–122.
- Ollerenshaw, K. (2006) Problems of consistency in automatic part-of-speech annotation of spoken language corpora. Journal of Empirical Corpus Methods 3(1): 19–51.
- Ollerenshaw, K. (2005) A computational approach to the identification of recurrent lexical patterns in newspaper discourse. Journal of Empirical Corpus Methods 2(2): 101–134.